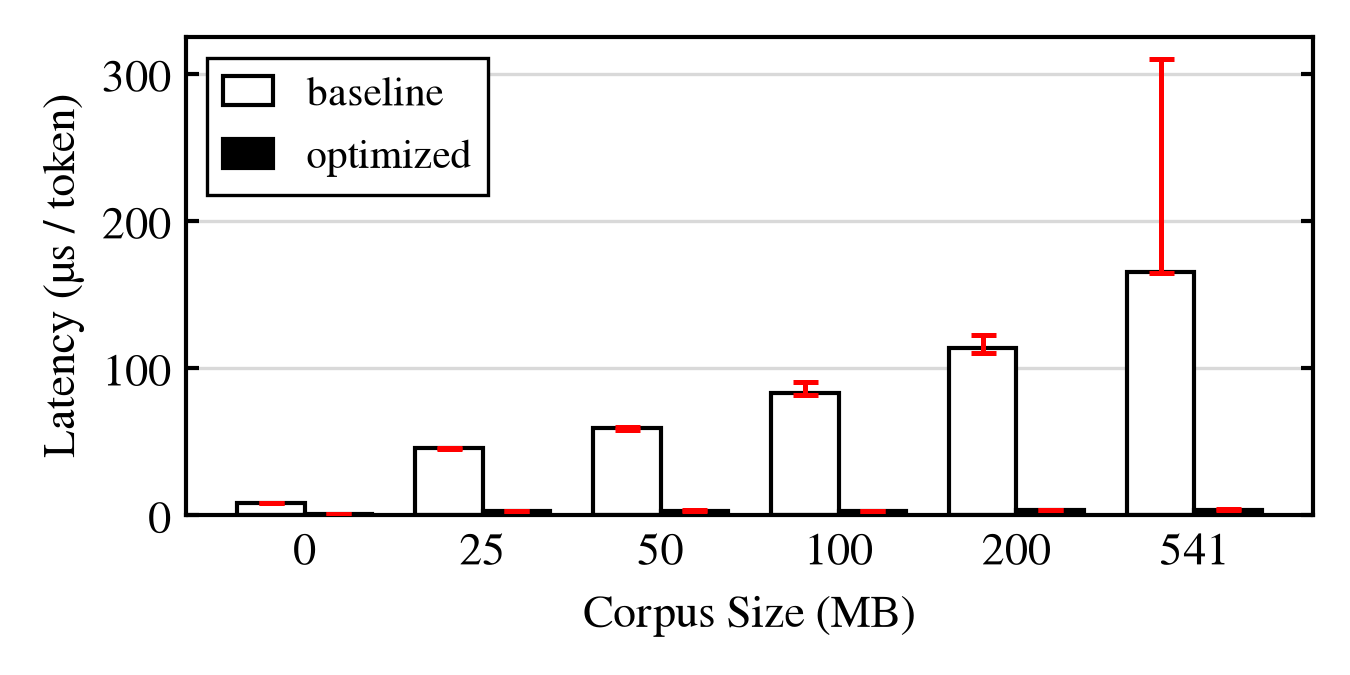
42x faster prompt lookup drafting in llama.cpp
The article describes a set of low-level optimizations in llama.cpp that make prompt lookup drafting up to 42x faster and use up to 2.6x less memory, with an additional PR pushing total speedups as high as 140x. For CIOs and IT leaders, the strategic takeaway is that inference efficiency improvements can materially reduce GPU/CPU spend, improve latency and throughput, and make self-hosted or edge AI deployments more practical at scale.
Hacker News3 min read