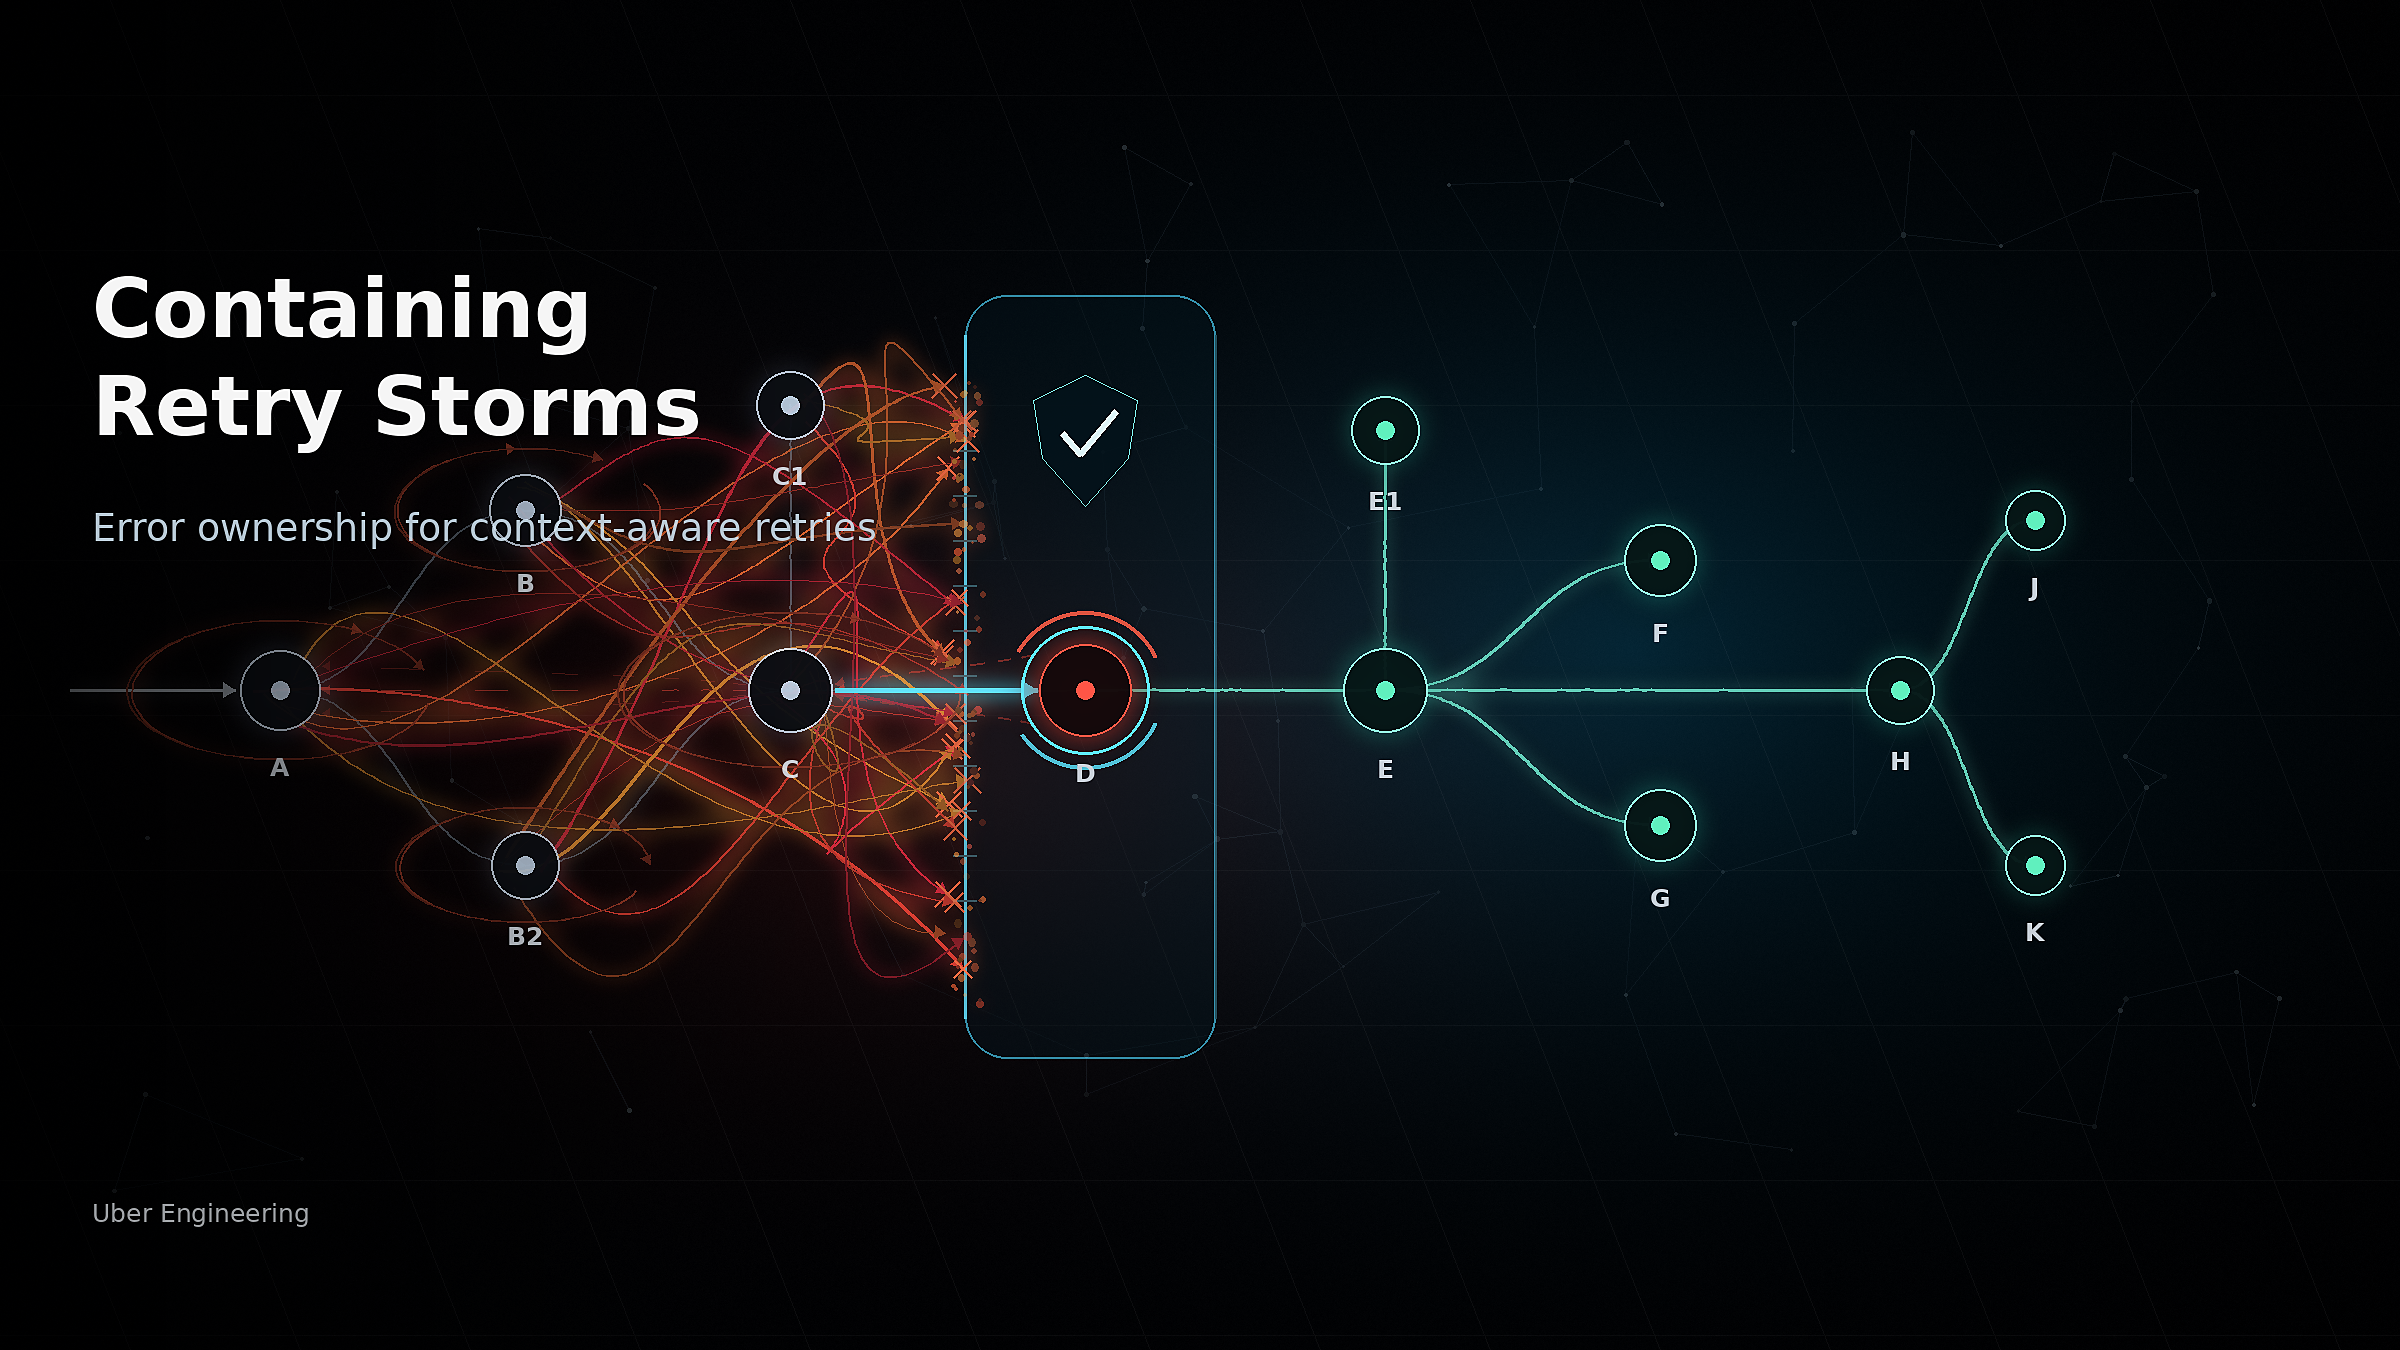
How Uber Protects Against Retry Storms
Uber’s approach shows that poorly controlled retries can turn a localized service failure into a stack-wide incident, harming uptime, customer experience, and brand trust. The strategic shift is from manual, service-by-service retry tuning to shared, context-aware infrastructure that uses retry budgets and error ownership to limit amplification while preserving availability. For IT organizations, this means platform teams need better dependency visibility, centralized resilience controls, and policies that distinguish between root-cause errors and propagated failures.
Hacker News3 min read