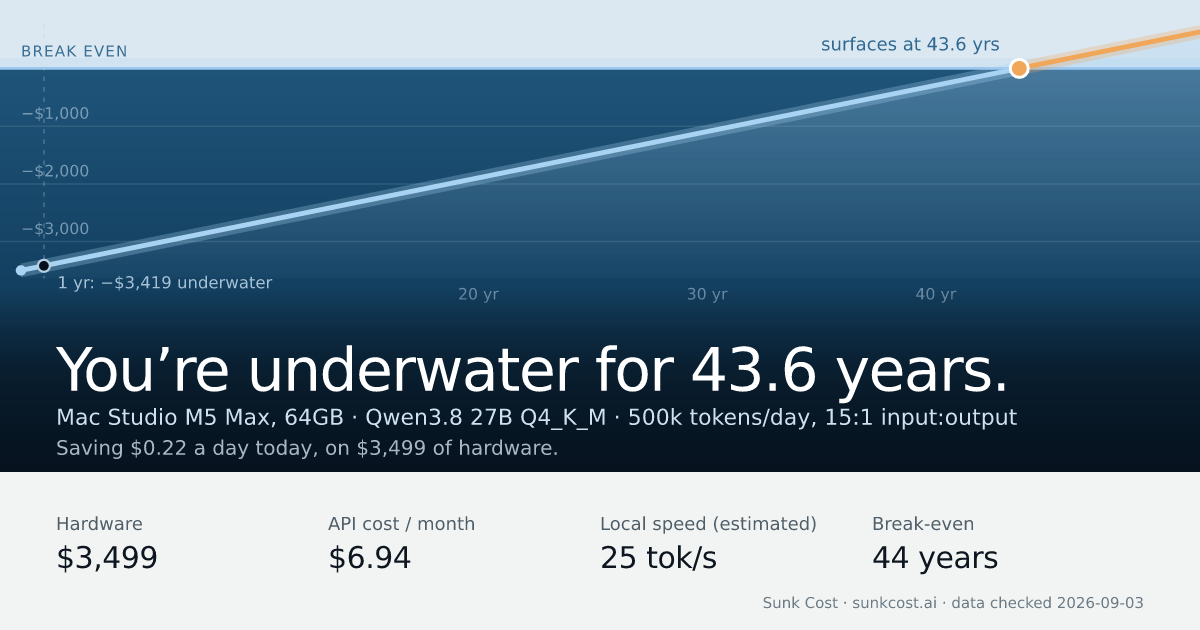
Show HN: Sunk Cost – How long until a local LLM rig pays for itself?
This article introduces a calculator that estimates when a local LLM rig pays for itself versus using cloud APIs, based on workload volume, model size, hardware cost, electricity, speed, and token usage. For CIOs and technology leaders, the strategic takeaway is that high-volume or privacy-sensitive AI workloads may justify shifting from recurring API spend to owned infrastructure, but only if IT can accurately model utilization, performance, and total cost of ownership. It highlights the need for IT organizations to make AI platform decisions with the same financial discipline used for other infrastructure investments, balancing cost, control, latency, and operational complexity.
Hacker News3 min read