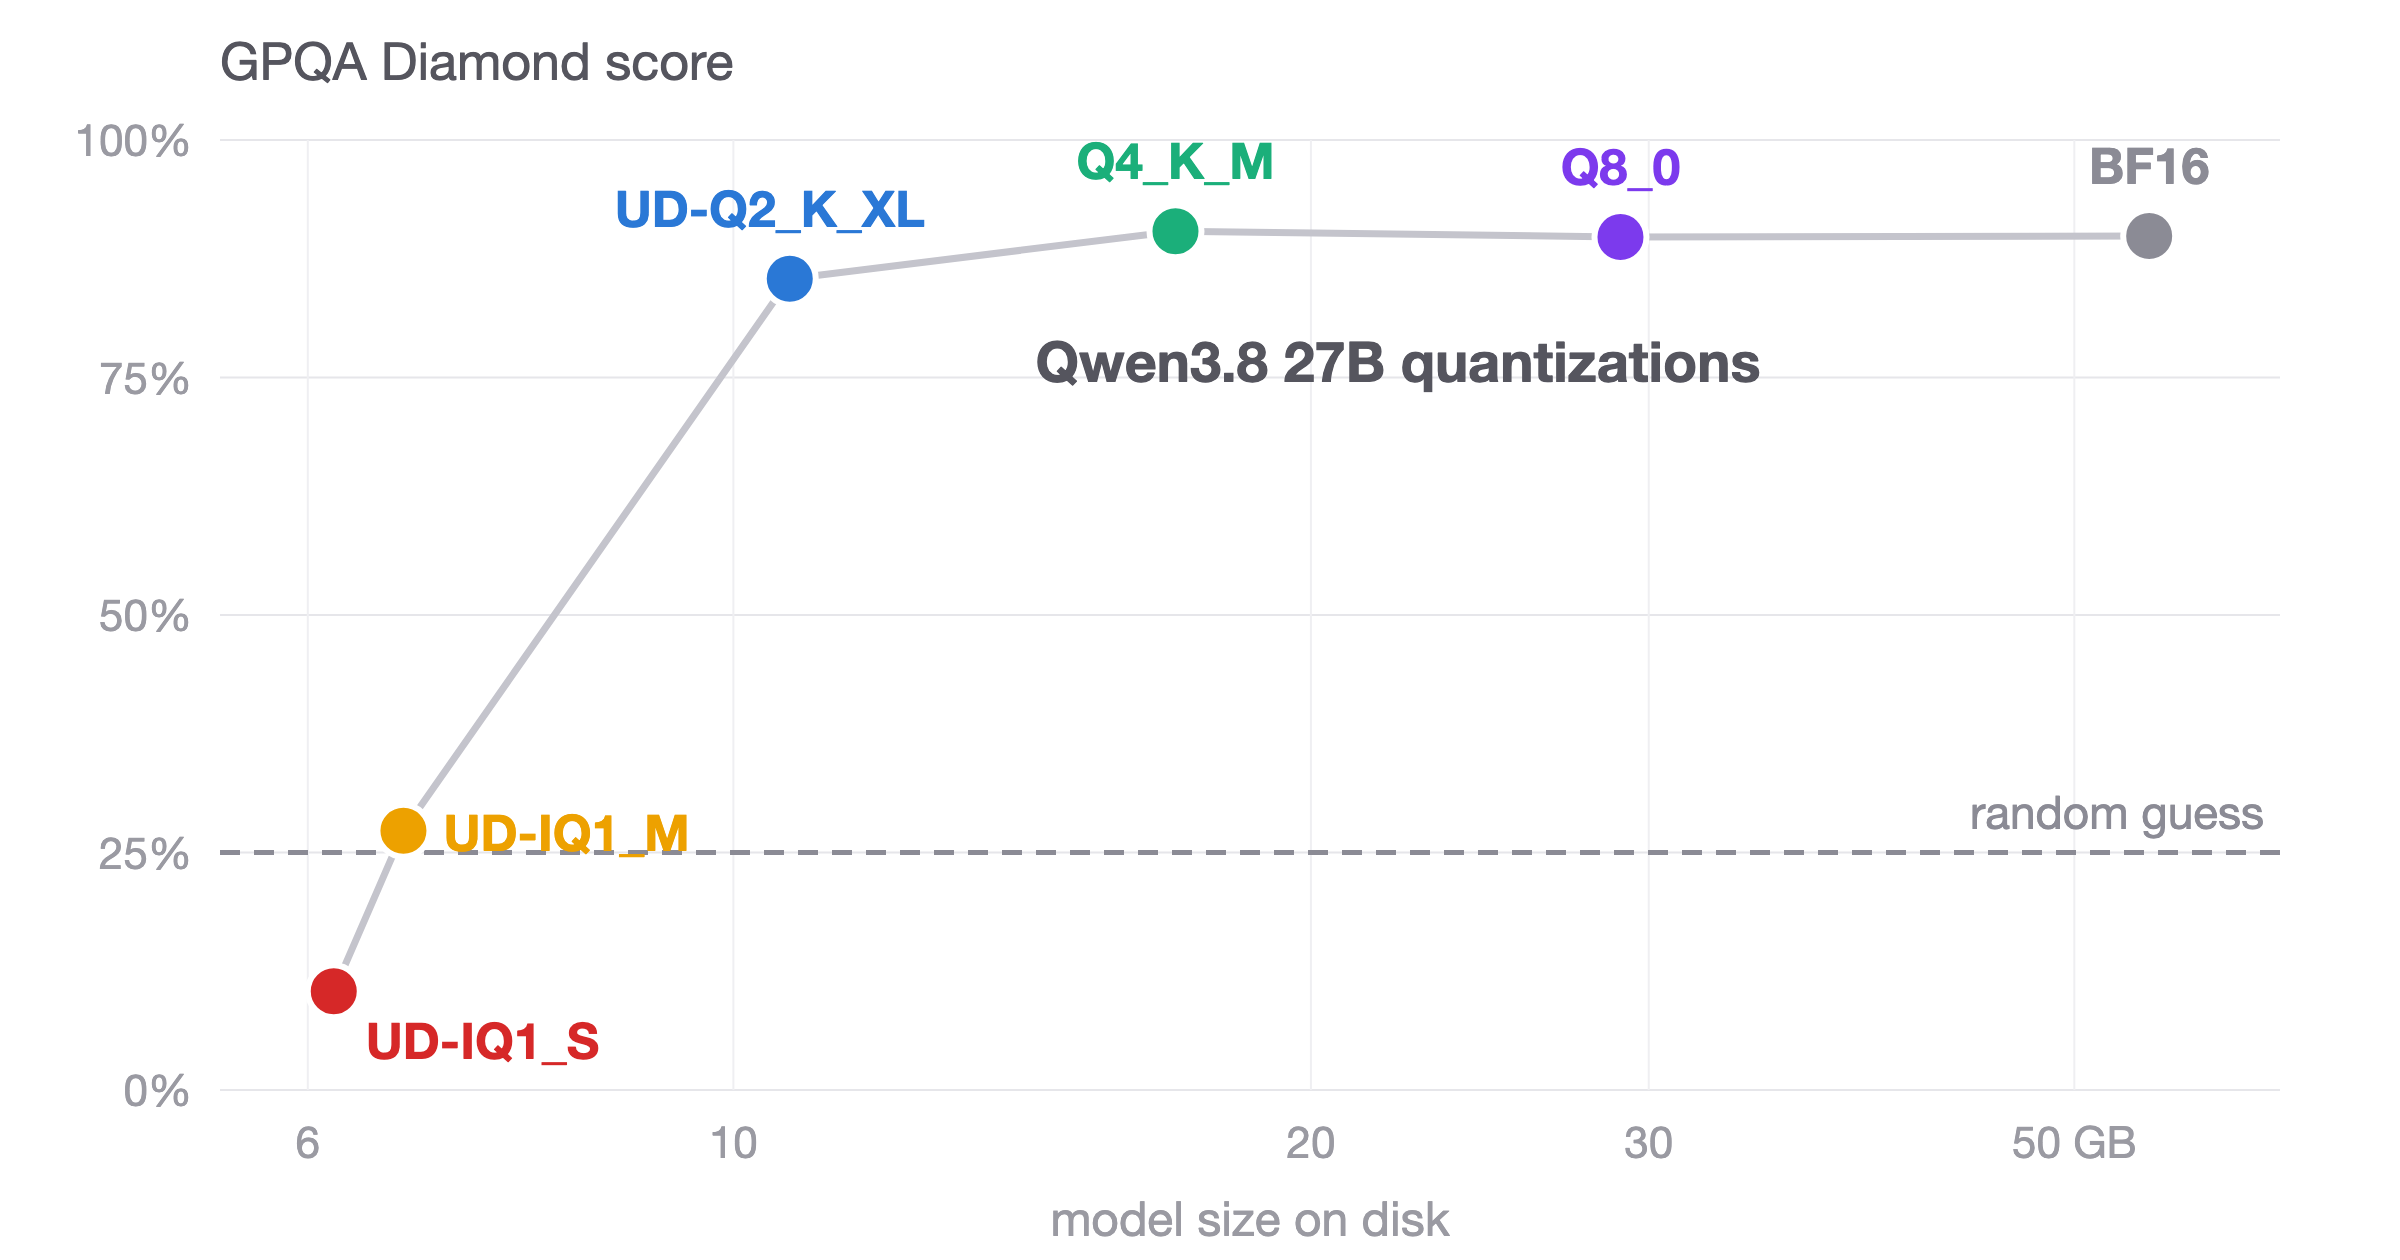
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
The article shows that CIOs can significantly reduce GPU infrastructure costs for Qwen3.8 27B without sacrificing quality by using 4-bit quantization, which performs nearly identically to the full BF16 model on knowledge, instruction-following, and agentic coding benchmarks while fitting on a 24 GB GPU. Strategically, this makes local and on-prem AI deployments more practical for IT organizations, but it also underscores that pushing compression too far creates a hard quality cliff: 2-bit is usable with some degradation, while 1-bit collapses and is not fit for production use.
Hacker News3 min read